 how-to
Strip HTML Tags From Text Online: A How-To Guide
Table of Contents
- Why You Need to Strip HTML Tags From Text Online
- How to Use a Browser-Based HTML Stripper Step by Step
- HTML to Plain Text Converter: What It Does and When to Use It
- How to Strip HTML Tags From a String Without Coding
- Remove HTML Formatting From Copied Text: Handling Links, Line Breaks, and Entities
- Privacy and Safety: Why Local Processing Matters
- Stripping HTML vs Full HTML-to-Text Conversion: Key Differences
- Common Mistakes When You Strip HTML Tags From Text Online
- Frequently Asked Questions
Last Updated: October 6, 2026
Why You Need to Strip HTML Tags From Text Online
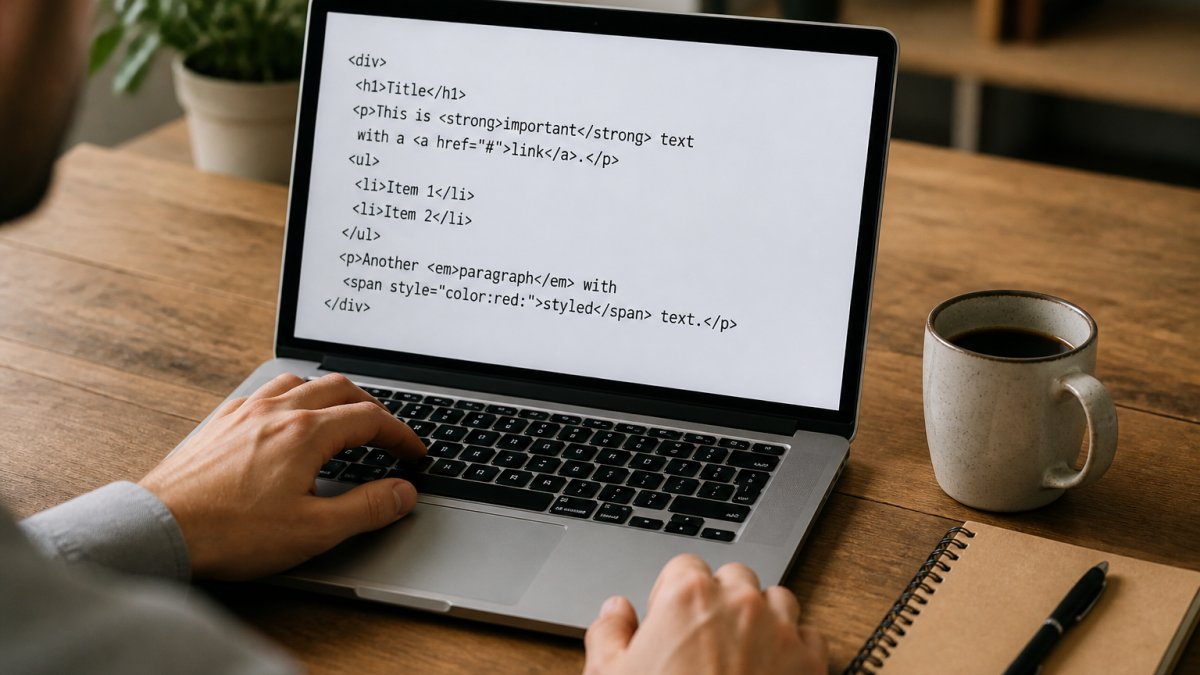
When you copy text from a web page, an email template, or a content management system, you rarely get just the words. You get the markup too: <div>, <span>, <p>, style="...", and a trail of closing tags. To strip HTML tags from text online is to remove that markup and leave only readable plain text.
This guide from TextUtility walks through the whole process: what a browser-based HTML stripper does and how to use one.
Here is the part most guides skip. Stripping tags and converting HTML to text are not the same job, and knowing which one you need saves real cleanup time later.
TextUtility's tools run entirely in your browser. Nothing gets uploaded, and there is no account to create. That matters if you handle client documents, unpublished manuscripts, or anything under an NDA.
Quick definitions, because the vocabulary gets sloppy fast:
- HTML markup is the code that structures a page: tags, attributes, and entity codes.
- Plain text is the readable content with no markup at all.
- An HTML stripper is the tool that removes the first and leaves the second.
How to Use a Browser-Based HTML Stripper Step by Step
A browser-based HTML stripper takes pasted markup and returns clean text in one pass. No install, no command line, no sign-up. You paste into one box and read the result in the other.
What You'll Need Before You Start
Almost nothing, which is the point. Here is the checklist:
- The HTML snippet or source code you want to clean
- A browser on desktop or phone
- A destination for the output (a document, a CMS field, or a spreadsheet)
- Two minutes
The one thing to decide first: do you need the links preserved, or do you want them gone entirely? That choice changes which options you pick.
Step-by-Step: Paste, Clean, Copy
- Copy the HTML source code. Grab it from your CMS, an email client, or a page's view-source.
- Paste it into the input text area. The tool accepts a single snippet or a long document.
- Choose your options. Decide whether to keep line breaks, keep hyperlinks as readable URLs, or remove all markup.
- Run the cleanup. Processing happens instantly, inside your browser.
- Check the output text area. Scan for stray entities like
&or collapsed spacing. - Copy or download the cleaned text into your destination.
Expected result: readable text with no tags, no attributes, and no leftover entity codes.
HTML to Plain Text Converter: What It Does and When to Use It
An HTML to plain text converter transforms a whole HTML document into readable text, keeping the structure a reader expects: paragraph breaks, list items, and headings as separate lines. A tag remover just deletes markup. The converter decides what the deleted markup meant.
That distinction shows up in practice. Strip the tags from a bulleted list and you often get one run-on line. Convert it properly and you get the list back, one item per line.
Use a converter when:
- You are moving web copy into a Word document or manuscript
- You need a clean text string for a CMS import
- You are running an SEO audit and want to read the text content without the code
- You are preparing source material for translation
Use a plain stripper when you only want the words and do not care about structure. Both are legitimate. Mixing them up is where people lose an afternoon.
How to Strip HTML Tags From a String Without Coding
You do not need a script to strip HTML tags from a string. A browser tool handles it, and for most writers, students, and editors that is the faster path.
Developers have other options. Every major language has libraries for markup removal, and regular expressions can handle simple cases.
For everyone else, here is a comparison:
| Approach | Best For | Setup | Handles Messy HTML |
|---|---|---|---|
| Browser-based tool | One-off cleanup, writers, students | None | Yes, for pasted content |
| Spreadsheet formula | Simple tags in a column of cells | Low | No, breaks on nesting |
| Script or library | Bulk files, automated pipelines | High | Yes, with a real parser |
| Manual deletion | A handful of tags | None | No, error-prone |
If you are cleaning one document, a browser tool can be efficient. If you are processing hundreds of HTML files on a schedule, a script may be more suitable.
Remove HTML Formatting From Copied Text: Handling Links, Line Breaks, and Entities
Removing HTML formatting from copied text is straightforward until you hit links, spacing, and entity codes. Those three are where clean output turns into a mess.
Preserving Hyperlinks and URLs
You have two sensible options, and one bad one.
- Keep the link text only. "Read the report" stays; the URL disappears.
- Keep the URL in plain form. "Read the report (https://example.com)" survives as readable text.
- Keep raw anchor tags. Almost never useful. It defeats the purpose of stripping.
For research notes and citations, keep the URL. For social media reformatting, drop it. Link text without a URL is fine when the destination is obvious or already cited elsewhere.
Fixing Whitespace and HTML Entities
Entity codes are the sneaky part. HTML uses & for an ampersand, for a non-breaking space, < and > for angle brackets, and dozens more.
Whitespace needs the same attention. Markup removal often leaves double spaces, orphaned blank lines, or tabs where a table used to be. Look for a tool that collapses whitespace and normalizes line breaks in the same pass.
Privacy and Safety: Why Local Processing Matters
Local processing means the tool runs the conversion inside your browser, using your own device. Your text never travels to a server. That is a meaningful difference from tools that upload your content, process it remotely, and store it somewhere you cannot see.
Why does it matter? Because the text people paste into these tools is often sensitive. Unpublished manuscripts. Client contracts. Student work under an academic integrity policy. Internal documentation with names and figures in it.
A remote tool asks you to trust an unknown party with all of it. A local tool does not ask at all.
TextUtility builds its tools this way on purpose. No sign-up, no upload, no stored copy. You paste, you clean, you close the tab. For anyone handling confidential documents, that is the whole argument.
The trade-off is that local processing means the tool depends on your device's resources. For enormous files, a desktop application may handle the load better.
Stripping HTML vs Full HTML-to-Text Conversion: Key Differences
Stripping and converting are related, but they answer different questions. Stripping asks, "What are the words?" Conversion asks, "What did this document say, and how was it arranged?"
Stripping removes tags and attributes and returns a text string. It is fast and blunt when structure does not matter.
Conversion interprets the markup first. It turns <h2> into a heading, <li> into a list item, and <p> into a paragraph break. The output is still plain text, but it preserves the document's shape.
For CMS imports, SEO audits, and anything a human will read, conversion is usually worth the extra step. For quick text extraction, stripping is enough.
Common Mistakes When You Strip HTML Tags From Text Online
Most bad output traces back to a handful of avoidable errors. Here are the ones we see most.
Pasting rendered text instead of source code. If you copy from the visible page, your clipboard often carries hidden markup. Copy from the source when you can.
Ignoring entity codes. Skipping entity decoding leaves & and scattered through your text. Always check the output.
Stripping before deciding about links. If you need URLs preserved, set that option first. Recovering them afterward means going back to the source.
Using the wrong tool for bulk work. A browser tool is ideal for one document. For hundreds of HTML files, a parser-based script is the right call.
Trusting the output without reading it. A scan can help catch issues.
Forgetting the privacy question. If your text is confidential, check whether the tool processes locally before you paste a single word.
Frequently Asked Questions
How do I strip HTML tags from text online?
Paste your HTML snippet into a browser-based HTML stripper, click the clean button, and copy the plain text output. The tool removes all markup, attributes, and tags, leaving only readable text. No coding or sign-up is required. Most tools process everything locally in your browser, so your pasted content never leaves your device.
Is it safe to paste confidential text into an online HTML stripper?
It depends on the tool. Some online tools send your text to a server for processing, which raises privacy concerns. Look for a browser-based tool that processes text locally, meaning nothing is uploaded. TextUtility, for example, runs entirely in your browser, so confidential client documents, academic papers, or code snippets stay on your machine.
Can I strip HTML tags from a string without coding?
Yes. A browser-based HTML tag remover lets you paste a text string containing HTML markup and instantly get clean plain text. You do not need to write regular expressions or use a programming language. The tool handles tags, attributes, and even HTML entities for you. Just paste, click, and copy the result.
How do I remove HTML formatting from copied text but keep the links?
Some HTML strippers offer options to preserve hyperlinks while removing other formatting. If your tool does not, you can manually convert anchor tags to plain URLs before stripping. For example, replace <a href="URL">link text</a> with "link text (URL)". This keeps the destination visible in the plain text output.
Cleaning markup by hand is slow, and most online tools ask you to upload your text to a server you cannot inspect. TextUtility takes the other approach: browser-based tools that run locally, need no sign-up, and work the same on a phone or a desktop. Paste your HTML, remove the tags, and copy the clean text in seconds.
Pick a tool.